GPU Servers
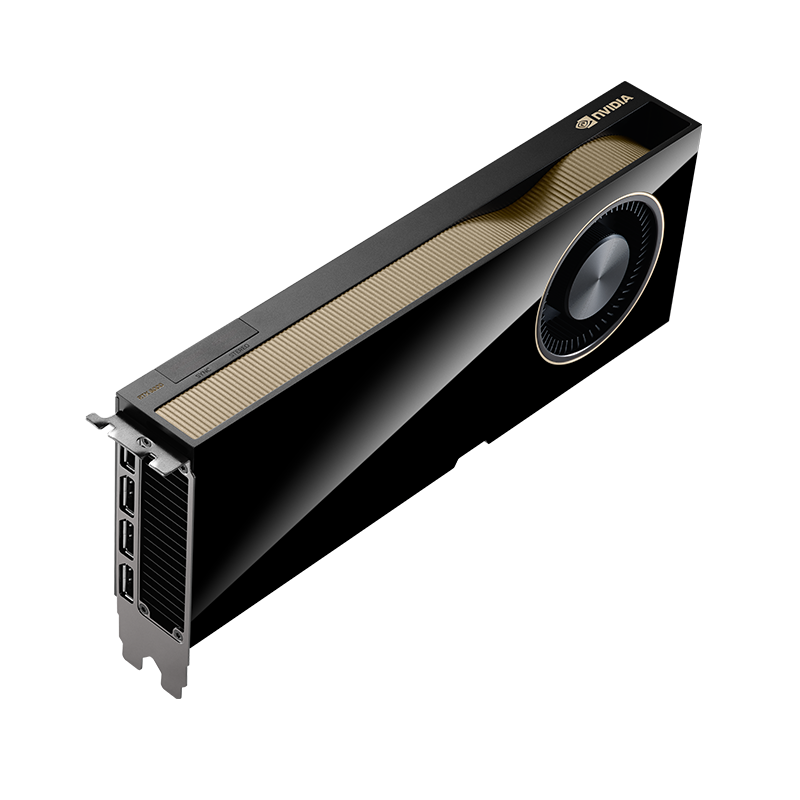
NVIDIA RTX 6000 Ada Servers
48 GB of GDDR6 memory per GPU supports medium-to-large model training and inference workloads with comfortable headroom.
Especificaciones clave
Cargas de trabajo ideales
Fine-Tuning up to 30B
Train and fine-tune models up to 30B+ parameters with 8x RTX 6000 Ada GPUs in a single server.
Especificaciones técnicas
| Chassis | 4U or 8U high density |
|---|---|
| CPU | 2x AMD EPYC or Intel Xeon |
Accelerate professional graphics, AI, visualization, rendering, and GPU-intensive workloads with NVIDIA RTX 6000 Ada servers. Powered by the NVIDIA Ada Lovelace architecture, these enterprise GPU servers combine high-performance compute, advanced ray tracing, AI acceleration, and large GPU memory to support demanding professional and data-center applications.
Designed for organizations that need reliable GPU acceleration in a server environment, NVIDIA RTX 6000 Ada servers are well suited for AI inference, machine learning, professional visualization, 3D rendering, digital twins, simulation, virtual workstations, and technical computing.
Built for AI and Professional Applications
The RTX 6000 Ada platform provides a versatile foundation for workloads that require both powerful GPU compute and professional graphics capabilities. Typical applications include:
Generative AI and AI inference
LLM inference and AI applications
Machine learning and model development
Professional 3D visualization
Real-time rendering
Ray tracing
CAD and engineering applications
Digital twins
Scientific visualization
Simulation and technical computing
Virtual workstations
Media and entertainment production
GPU-accelerated enterprise applications
NVIDIA Ada Lovelace Architecture
Built on the NVIDIA Ada Lovelace architecture, the RTX 6000 Ada Generation is designed to deliver significant performance for professional visualization and AI-accelerated workloads.
Its combination of CUDA acceleration, RT Cores, and Tensor Cores enables organizations to run a broad range of applications on a single professional GPU platform, from AI inference and rendering to engineering visualization and simulation.
Large GPU Memory for Demanding Workloads
The NVIDIA RTX 6000 Ada features a large GPU memory capacity, making it suitable for complex 3D scenes, high-resolution visualization, AI models, rendering workloads, and other memory-intensive applications.
For enterprises running professional applications remotely, RTX 6000 Ada servers can provide dedicated GPU resources for users and workloads without requiring high-end GPU hardware at every workstation.
Enterprise GPU Server Infrastructure
RTX 6000 Ada servers can be deployed in data centers, private clouds, enterprise environments, research facilities, engineering organizations, media studios, and virtual workstation infrastructures.
They provide a flexible way to centralize GPU resources and deliver accelerated applications to users across an organization.
Key Highlights
NVIDIA RTX 6000 Ada Generation GPU
Professional GPU server platform
NVIDIA Ada Lovelace architecture
Advanced AI acceleration with Tensor Cores
Hardware-accelerated ray tracing
Large GPU memory capacity
Designed for AI inference and machine learning
Ideal for professional visualization and 3D rendering
Suitable for CAD, engineering, simulation, and digital twins
Supports virtual workstation deployments
Enterprise-ready GPU infrastructure
Whether you are deploying AI inference, professional visualization, 3D rendering, engineering applications, digital twins, or virtual workstations, NVIDIA RTX 6000 Ada servers provide a powerful and flexible GPU infrastructure platform for demanding enterprise workloads.
Preguntas frecuentes
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
¿Listo para empezar?
Construya su infraestructura de IA con confianza
Hable con nuestro equipo de infraestructura empresarial. Obtenga asesoramiento experto, precios de GPU y un plan de despliegue a medida — sin compromiso.