AI Servers
AI Server 8 GPU
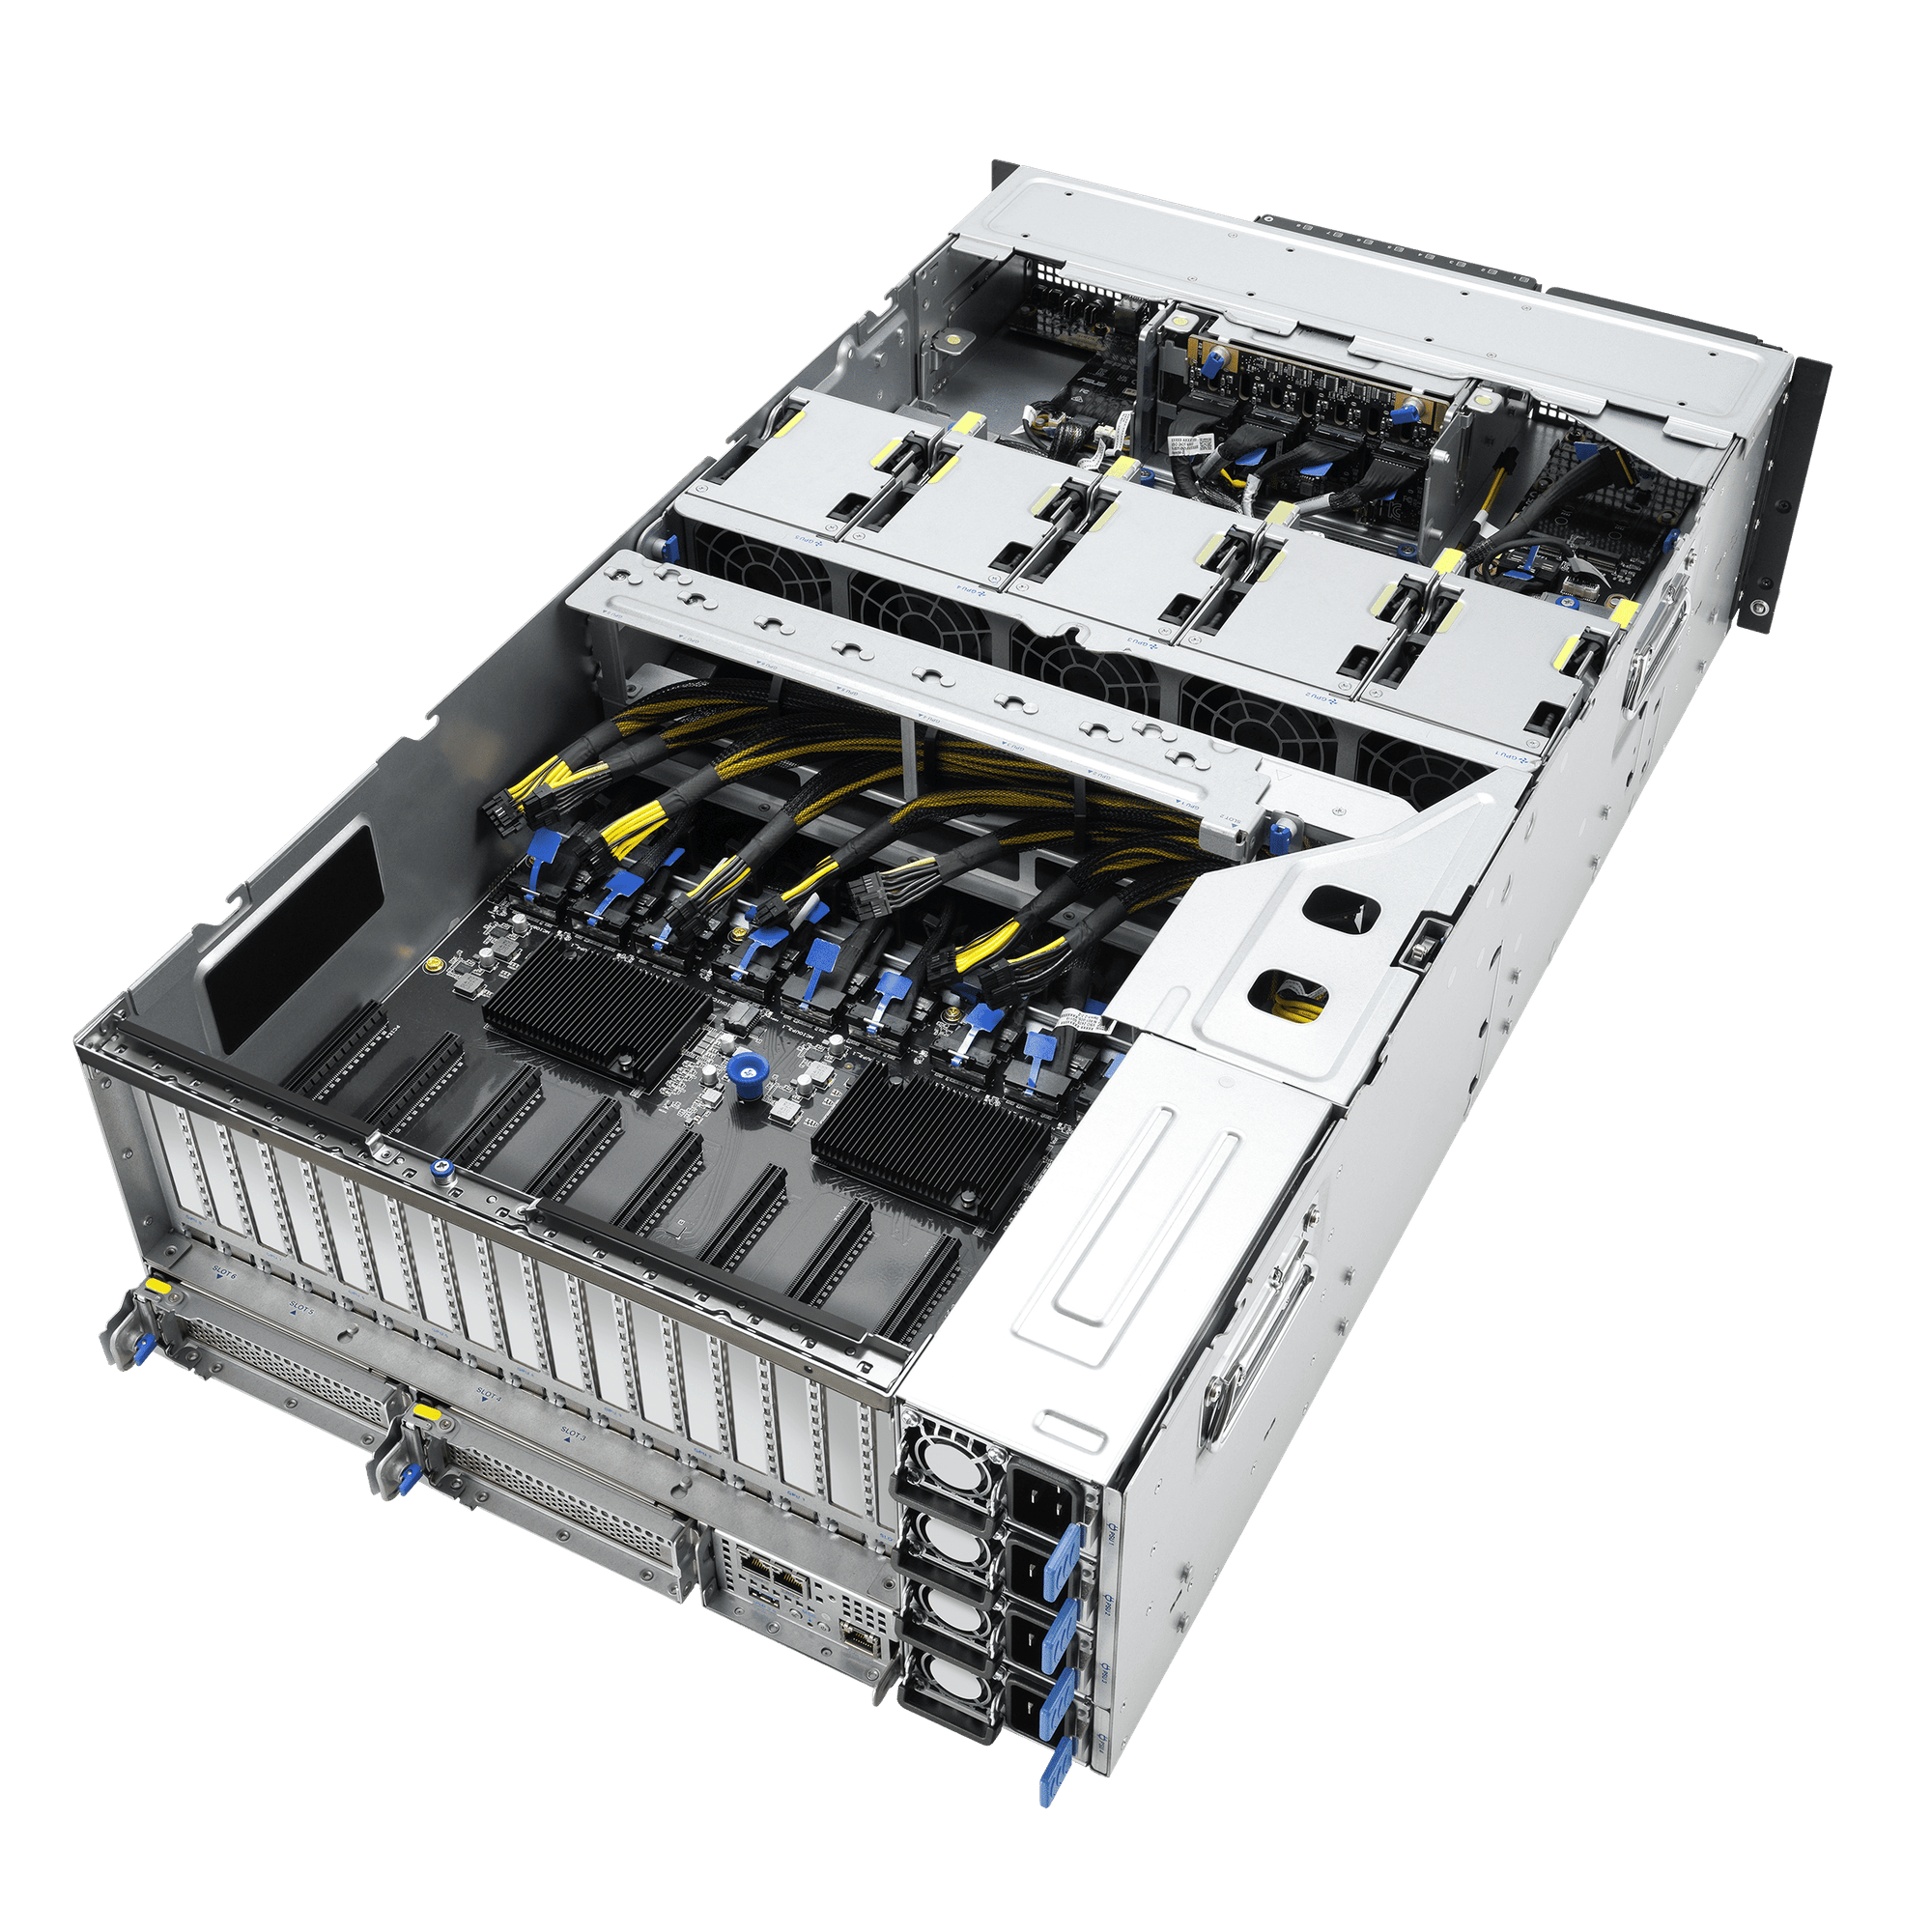
Up to 8 NVIDIA GPUs including H200 NVL and RTX PRO 6000 Blackwell in a single server, with dual AMD EPYC 9005 processors for balanced CPU + GPU workloads.
Especificaciones clave
Cargas de trabajo ideales
LLM Training
Train large language models with 8x GPU parallelism.
Multi-Model Serving
Serve multiple AI models simultaneously across 8 independent GPUs.
Especificaciones técnicas
| Chassis | 4U or 8U Rackmount |
|---|---|
| Memory | Up to 3 TB DDR5 |
| Networking | Up to 4x 400 Gb |
Power demanding artificial intelligence workloads with an 8 GPU AI server engineered for large-scale LLM training, inference, fine-tuning, generative AI, and high-performance computing. By combining eight GPUs in a single high-density system, these servers provide the compute capacity and memory resources required for advanced enterprise AI, large language models, scientific computing, and production-scale AI applications.
An 8 GPU AI server is designed for organizations that need substantial GPU performance within a single server platform. Compared with smaller 1 GPU, 2 GPU, or 4 GPU configurations, an eight-GPU system provides greater accelerator density and can enable highly parallel workloads to run efficiently across multiple GPUs.
Built for Large-Scale AI Workloads
Eight-GPU servers are particularly well suited for demanding workloads such as:
Large language model (LLM) training
LLM inference and serving
Generative AI
Foundation model development
AI model fine-tuning
Reinforcement learning
Retrieval-augmented generation (RAG)
AI agents and reasoning models
Multimodal AI
Computer vision
Natural language processing
Scientific computing
High-performance computing (HPC)
GPU-accelerated analytics
High-Density Multi-GPU Architecture
An 8 GPU server provides a tightly integrated environment where multiple accelerators can work together on parallel AI workloads. Depending on the selected platform, GPU interconnect technologies can provide high-bandwidth communication between GPUs, helping reduce communication bottlenecks in distributed training and other multi-GPU applications.
This architecture is particularly valuable for large AI models and memory-intensive workloads that benefit from multiple GPUs operating as a coordinated compute platform.
Enterprise AI Infrastructure
8 GPU AI servers are an excellent foundation for enterprise AI clusters, AI factories, private AI clouds, research laboratories, universities, cloud service providers, and high-performance computing environments.
Organizations can deploy these systems for model development and experimentation as well as production inference and enterprise AI applications. Their high GPU density can also help consolidate compute resources into fewer physical systems, depending on workload and infrastructure requirements.
Flexible GPU Configurations
An 8 GPU AI server can be configured with different generations and classes of accelerators to meet specific requirements for GPU memory, compute performance, power consumption, and workload compatibility.
Depending on the platform, configurations may support advanced GPU interconnect technologies, high-speed networking, large system memory, and fast local storage to create a complete infrastructure foundation for demanding AI workloads.
Key Highlights
8 GPU AI server configuration
High-density multi-GPU architecture
Designed for LLM training and inference
Ideal for generative AI and foundation models
Supports fine-tuning, RAG, AI agents, and multimodal workloads
High GPU compute and memory capacity
Suitable for enterprise AI and HPC environments
Designed for demanding parallel workloads
Flexible GPU, networking, storage, and system configurations
Strong foundation for scalable AI infrastructure
Whether you are training large language models, deploying high-throughput inference, developing generative AI applications, or running advanced scientific workloads, an 8 GPU AI server provides the high-performance accelerator infrastructure needed to support modern AI at scale.
Preguntas frecuentes
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
¿Listo para empezar?
Construya su infraestructura de IA con confianza
Hable con nuestro equipo de infraestructura empresarial. Obtenga asesoramiento experto, precios de GPU y un plan de despliegue a medida — sin compromiso.