GPU Servers
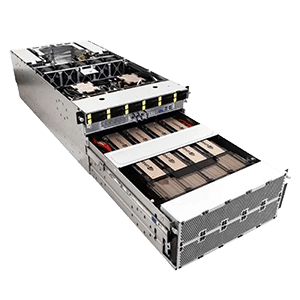
NVIDIA HGX H200 Servers
141 GB HBM3e per GPU — nearly double the capacity of H100, enabling larger models in a single system with widely available lead times.
Especificaciones clave
Cargas de trabajo ideales
Large-Context Inference
Serve long-context models without excessive tensor parallelism.
Especificaciones técnicas
| Form Factor | 8U air cooled |
|---|---|
| CPU | 2x Intel Xeon or AMD EPYC |
| Networking | 8x 400 Gb NDR InfiniBand |
Accelerate demanding AI and high-performance computing workloads with NVIDIA HGX H200 servers, purpose-built for enterprise LLM training, fine-tuning, inference, generative AI, and accelerated computing. Combining the NVIDIA H200 GPU platform with high-bandwidth GPU interconnect technology, HGX H200 systems provide the compute performance and GPU memory capacity required for modern AI infrastructure.
Designed for organizations deploying large-scale AI applications, HGX H200 servers deliver a powerful multi-GPU architecture for workloads that require substantial GPU memory, high throughput, and fast GPU-to-GPU communication. These systems are an ideal foundation for enterprise AI clusters, AI factories, research environments, and high-performance computing infrastructure.
Built for Large-Scale AI Workloads
NVIDIA H200 GPUs are designed for memory-intensive AI and HPC applications. An HGX H200 server can integrate multiple H200 GPUs into a tightly coupled system, making it well suited for computationally intensive workloads such as:
Large language model (LLM) training
LLM inference and serving
Generative AI
Foundation model development
AI model fine-tuning
Retrieval-augmented generation (RAG)
AI agents and reasoning workloads
Multimodal AI
Natural language processing
Computer vision
Scientific computing
High-performance computing (HPC)
High-Bandwidth GPU Infrastructure
HGX H200 platforms are engineered around high-performance GPU interconnects that enable efficient communication between GPUs within the server. This is especially important for distributed AI workloads where model training and inference depend on frequent exchange of data between accelerators.
The result is a highly capable multi-GPU AI server platform designed to keep demanding workloads moving efficiently while providing the GPU resources needed for increasingly large AI models.
Enterprise-Ready NVIDIA H200 Servers
NVIDIA HGX H200 servers are available through leading server OEMs and system partners, providing organizations with flexible options for deploying enterprise GPU infrastructure. They can serve as building blocks for dedicated AI clusters, private AI clouds, research environments, and production-scale inference platforms.
Whether you are expanding an existing GPU cluster or building a new AI infrastructure environment, NVIDIA HGX H200 servers provide a powerful platform for accelerating the development and deployment of next-generation AI applications.
Key Highlights
NVIDIA HGX H200 server platform
Multi-GPU architecture for enterprise AI
NVIDIA H200 GPUs with high-bandwidth GPU memory
High-speed GPU-to-GPU interconnect
Optimized for LLM training and inference
Ideal for generative AI and foundation models
Suitable for fine-tuning, RAG, AI agents, and multimodal workloads
Designed for AI data centers and HPC environments
Enterprise-grade foundation for scalable GPU infrastructure
Available through OEM and NVIDIA partner ecosystems
From LLM training and generative AI to production inference and scientific computing, NVIDIA HGX H200 servers provide the high-performance GPU infrastructure required to run some of today's most demanding accelerated workloads.
Preguntas frecuentes
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
¿Listo para empezar?
Construya su infraestructura de IA con confianza
Hable con nuestro equipo de infraestructura empresarial. Obtenga asesoramiento experto, precios de GPU y un plan de despliegue a medida — sin compromiso.