GPU Servers
NVIDIA HGX B300 Servers
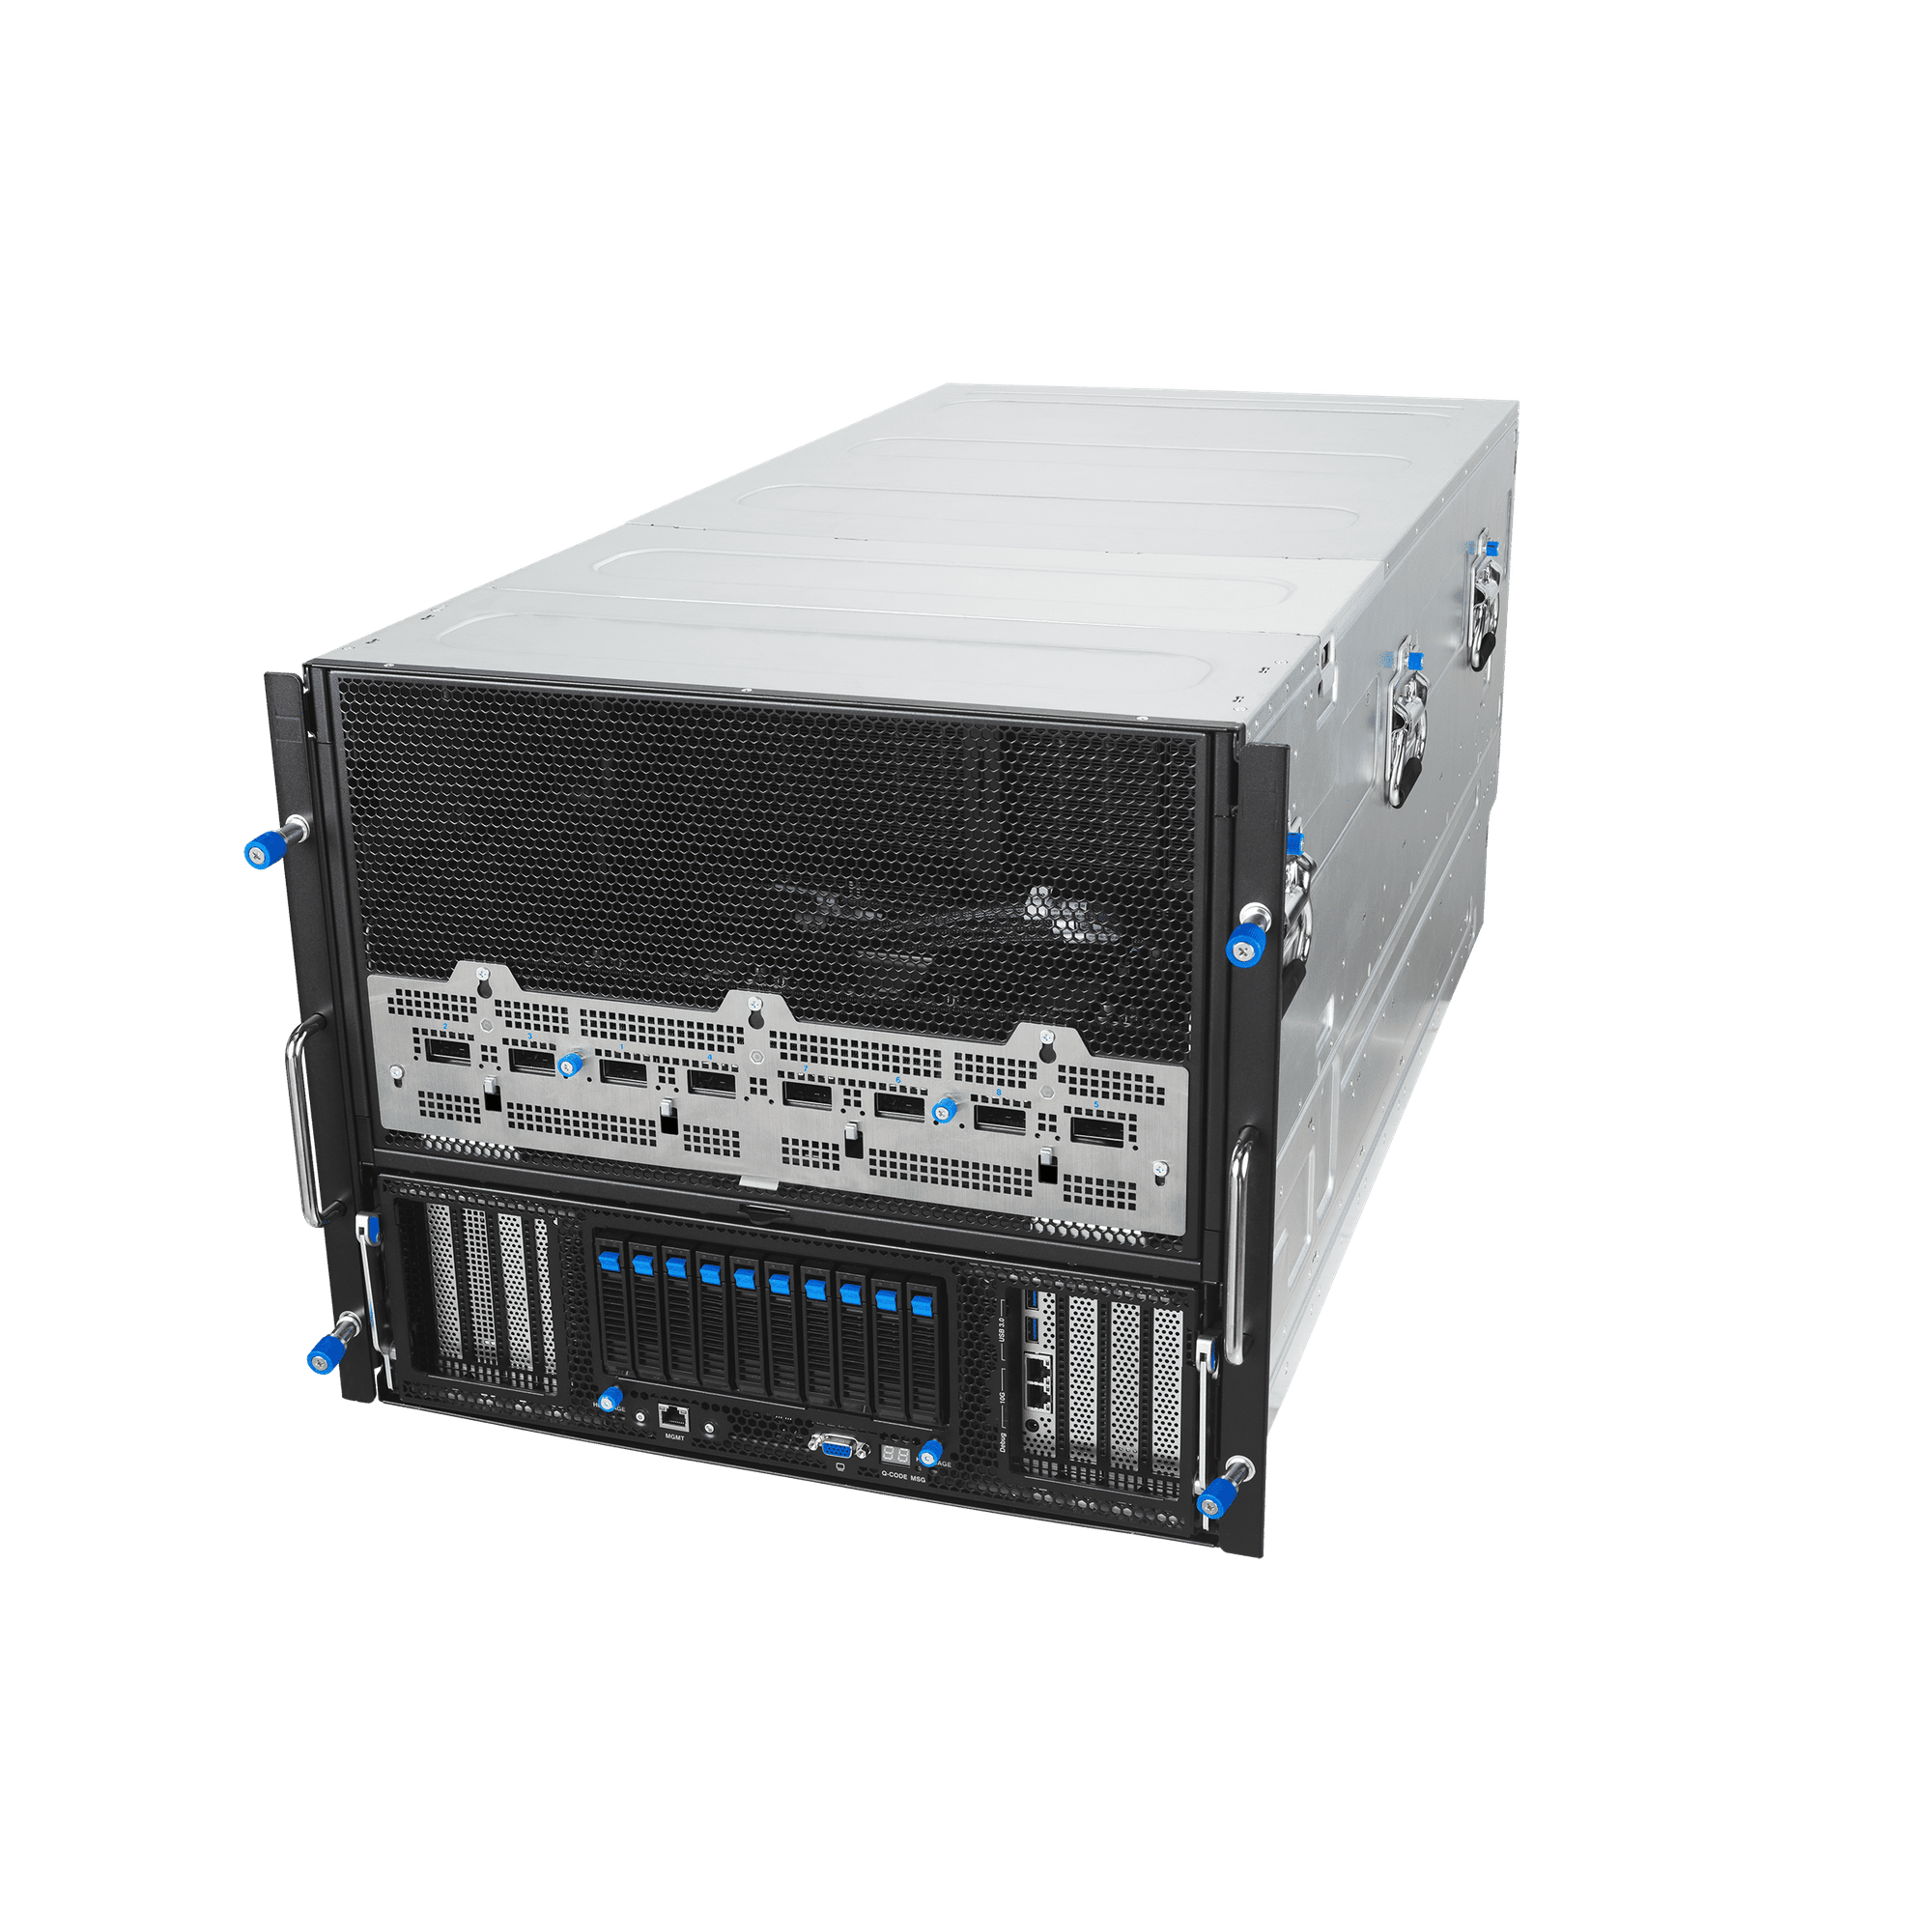
OEM HGX B300 baseboard systems from Supermicro, Dell and partner vendors — Blackwell Ultra GPUs and NVLink fabric delivering record intra-node bandwidth.
주요 사양
적합한 워크로드
Rack-Scale Training
Architecture optimised for reasoning, inference, and high-throughput production clusters.
기술 사양
| Form Factor | 8U / 10U air or liquid cooled |
|---|---|
| CPU Options | Intel Xeon 6 or AMD EPYC 9005 |
| Networking | Up to 8x 400 Gb + 2x 200 Gb management |
Deploy next-generation enterprise AI infrastructure with OEM HGX B300 baseboard systems from Supermicro, Dell, and leading partner vendors, powered by NVIDIA Blackwell Ultra GPUs and advanced NVLink fabric. Designed for the most demanding AI and accelerated-computing workloads, these systems deliver exceptional GPU density, high-bandwidth interconnects, and record intra-node communication performance for large-scale AI models.
Built around the NVIDIA HGX B300 platform, these AI server systems are engineered to accelerate large language model (LLM) training, generative AI, inference, fine-tuning, scientific computing, and high-performance computing (HPC). The combination of Blackwell Ultra GPU architecture and NVLink technology enables GPUs within a node to communicate at extremely high bandwidth, helping reduce communication bottlenecks and improve the efficiency of distributed AI workloads.
NVIDIA Blackwell Ultra for Next-Generation AI
The NVIDIA Blackwell Ultra GPU platform is designed for increasingly large and complex AI workloads, including trillion-parameter-class models, advanced generative AI, reasoning models, multimodal applications, and high-throughput inference.
HGX B300 systems provide enterprises and AI infrastructure operators with a powerful foundation for scaling compute-intensive workloads while maintaining high GPU-to-GPU communication performance.
High-Bandwidth NVLink Fabric
A key advantage of HGX B300 infrastructure is its high-performance NVLink GPU interconnect fabric. By providing extremely high-bandwidth communication between GPUs inside the server, NVLink helps accelerate workloads where frequent GPU-to-GPU data exchange is critical.
This is particularly important for:
LLM pre-training and post-training
Large-scale model fine-tuning
Generative AI inference
Reasoning and agentic AI
Multimodal AI
Transformer-based workloads
High-performance computing
Scientific simulations
AI model serving
GPU-accelerated analytics
For distributed AI applications, faster intra-node communication can help keep GPUs better utilized and reduce the impact of communication overhead during demanding parallel workloads.
OEM HGX B300 Systems from Leading Vendors
HGX B300 baseboard systems are available through OEM platforms from Supermicro, Dell, and partner vendors, giving organizations multiple deployment options for building enterprise-grade AI infrastructure.
These systems are suited to data centers, AI cloud providers, research institutions, and enterprises seeking a high-performance foundation for next-generation GPU clusters.
Built for Enterprise AI at Scale
As AI models continue to increase in size and complexity, conventional server architectures can become constrained by GPU memory, interconnect bandwidth, and communication overhead. HGX B300 systems with Blackwell Ultra GPUs and NVLink fabric are designed to address these requirements with a tightly integrated GPU architecture optimized for large-scale accelerated computing.
Organizations can use these platforms to build infrastructure for AI factories, LLM clusters, generative AI platforms, enterprise inference, model development, and advanced HPC applications.
Key Highlights
NVIDIA HGX B300 baseboard platform
NVIDIA Blackwell Ultra GPUs
High-bandwidth NVLink GPU interconnect
Record-class intra-node GPU communication bandwidth
OEM systems from Supermicro, Dell, and partner vendors
Designed for enterprise AI and HPC
Optimized for LLM training, inference, and fine-tuning
Ideal for generative AI, reasoning models, and multimodal workloads
High-performance infrastructure for large-scale GPU clusters
Suitable for AI data centers, cloud providers, research, and enterprise deployments
With Blackwell Ultra GPUs, HGX B300 architecture, and NVLink fabric, these systems provide a next-generation platform for organizations building high-performance AI infrastructure capable of supporting the rapidly growing demands of enterprise AI and large-scale model workloads.
자주 묻는 질문
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
시작할 준비가 되셨나요?
AI 인프라를 구축하세요 확신을 가지고
엔터프라이즈 인프라 팀과 상담하세요. 전문가의 조언, GPU 가격, 맞춤형 배포 계획을 받아보세요 — 별도의 약정은 필요 없습니다.