NVIDIA DGX
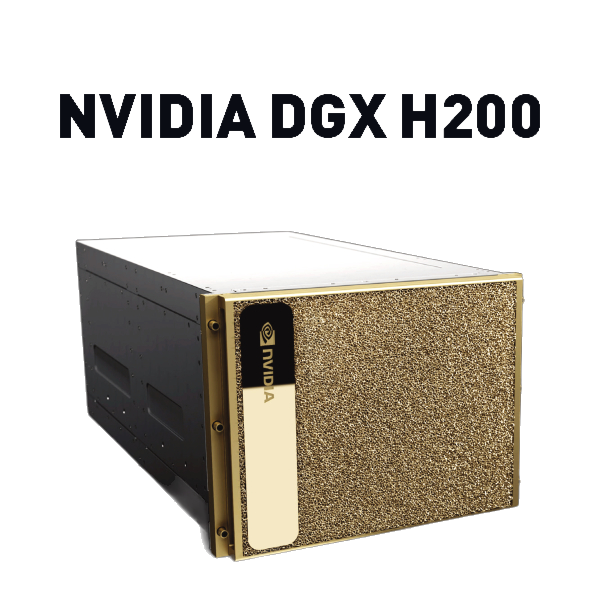
NVIDIA DGX H200
Proven Hopper-generation AI supercomputer with 8x H200 GPUs and 1.1 TB of HBM3e — the workhorse for enterprise LLM training and inference with shorter lead times.
Wichtigste Spezifikationen
Ideale Workloads
LLM Inference at Scale
141 GB per GPU lets 70B+ models run without aggressive sharding.
Enterprise Fine-Tuning
Domain adaptation of open-weight models on-premises.
Technische Daten
| CPU | 2x Intel Xeon Platinum 8480C |
|---|---|
| GPU | 8x NVIDIA H200 SXM 141 GB |
| System Memory | 2 TB DDR5 |
| Networking | 8x 400 Gb InfiniBand |
Accelerate enterprise AI workloads with a proven Hopper-generation AI supercomputer powered by 8x NVIDIA H200 GPUs and 1.1 TB of HBM3e memory. Designed as a high-performance workhorse for demanding large language model (LLM) training, fine-tuning, inference, and generative AI workloads, this platform delivers the compute density, GPU memory capacity, and scalability required for modern AI infrastructure.
Built around NVIDIA H200 GPUs, the system combines massive GPU compute performance with high-bandwidth HBM3e memory to efficiently handle memory-intensive AI workloads. With eight H200 GPUs in a single system, enterprises can consolidate demanding AI jobs, reduce infrastructure complexity, and accelerate model development from experimentation and fine-tuning through production inference.
The 1.1 TB of total HBM3e GPU memory provides substantial capacity for large models, extensive datasets, high-throughput inference, and complex training workloads. This makes the platform particularly well suited for organizations running enterprise LLMs, generative AI applications, retrieval-augmented generation (RAG), AI agents, natural language processing, computer vision, and other GPU-intensive workloads.
Built for Enterprise LLM Training and Inference
Whether you are training models from scratch, fine-tuning existing foundation models, or deploying LLMs at scale, this 8x NVIDIA H200 GPU server provides a powerful foundation for enterprise AI. Its high GPU density enables organizations to run computationally intensive workloads while taking advantage of the large memory footprint available across the system.
Typical workloads include:
Large language model (LLM) training
LLM fine-tuning and instruction tuning
Generative AI model development
High-performance LLM inference
RAG and AI agent workloads
Transformer-based model training
Natural language processing
Computer vision and multimodal AI
AI research and development
Enterprise machine learning
Model evaluation and benchmarking
Proven Hopper-Generation Architecture
Based on the NVIDIA Hopper architecture, this AI supercomputer is engineered for demanding accelerated-computing environments. The combination of 8x H200 GPUs and 1.1 TB of HBM3e creates a high-density platform for organizations that need substantial GPU resources without building a large distributed cluster from the ground up.
For enterprise AI teams, this architecture can help shorten the path from infrastructure deployment to productive AI workloads. The platform is particularly attractive for organizations looking for a ready-to-deploy GPU infrastructure solution with shorter lead times, allowing teams to scale AI initiatives faster and avoid unnecessary delays associated with designing and assembling custom GPU clusters.
A High-Performance Workhorse for AI Infrastructure
From AI startups and research teams to large enterprises, this H200 GPU supercomputer provides the compute and memory resources needed to support increasingly demanding AI workloads. Its eight-GPU configuration offers a strong balance between GPU density, memory capacity, performance, and operational simplicity.
If your organization is looking for NVIDIA H200 servers, 8-GPU AI systems, enterprise GPU infrastructure, LLM training servers, or high-performance AI compute, this platform provides a powerful foundation for deploying next-generation AI applications.
Key Highlights:
8x NVIDIA H200 GPUs
1.1 TB total HBM3e GPU memory
NVIDIA Hopper-generation architecture
Designed for enterprise LLM training and inference
Ideal for generative AI and foundation-model workloads
Suitable for fine-tuning, RAG, AI agents, and ML workloads
High-density GPU infrastructure for enterprise environments
Shorter lead time compared with lengthy custom infrastructure deployments
Built as a reliable AI supercomputer workhorse for demanding compute workloads
Whether the goal is to accelerate LLM development, fine-tuning, inference, generative AI, or enterprise machine learning, this 8x H200 AI supercomputer provides the high-memory, high-performance GPU infrastructure required to move demanding AI projects from development to production.
Häufige Fragen
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
Bereit für den Start?
Bauen Sie Ihre KI-Infrastruktur Mit Zuversicht
Sprechen Sie mit unserem Enterprise-Infrastrukturteam. Erhalten Sie fachkundige Beratung, GPU-Preise und einen individuellen Bereitstellungsplan — unverbindlich.