NVIDIA MGX
NVIDIA MGX GB200 NVL72
Rack-scale AI supercomputer. All 72 GPUs are interconnected via fifth-gen NVLink, enabling seamless scaling of trillion-parameter model training.
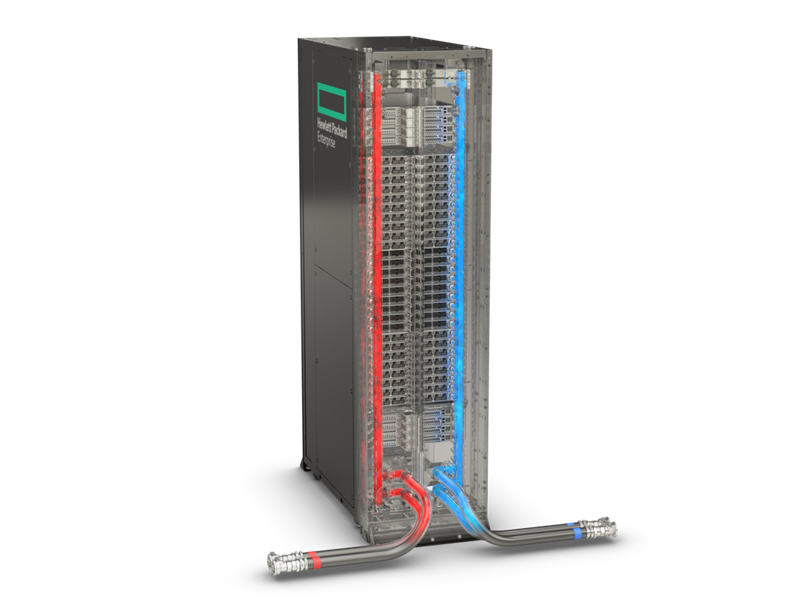
Key specifications
Ideal workloads
Frontier Model Training
Train the largest foundation models at rack scale with unprecedented GPU-to-GPU bandwidth.
Technical specifications
| Form Factor | Full rack, liquid cooled |
|---|---|
| Rack Power | ~120 kW |
| Interconnect | NVLink Switch System |
Accelerate next-generation AI workloads with the NVIDIA MGX GB200 NVL72, a high-density AI computing platform designed for large-scale LLM training, inference, generative AI, reasoning models, and accelerated computing. Combining NVIDIA Blackwell architecture with a tightly integrated multi-GPU and NVLink infrastructure, the GB200 NVL72 is built to deliver exceptional performance for the most demanding AI workloads.
The GB200 NVL72 brings together 72 Blackwell GPUs in a rack-scale architecture, creating a powerful unified compute environment for workloads that require massive GPU compute, high memory capacity, and extremely high-bandwidth GPU-to-GPU communication.
Built for Large-Scale AI
The NVIDIA MGX GB200 NVL72 is designed for organizations running increasingly complex AI models and applications. Its rack-scale architecture is particularly suited to workloads that can benefit from tightly coupled GPU resources, including:
Large language model (LLM) training
Large-scale LLM inference
Generative AI
Foundation model development
Reasoning and agentic AI
AI model fine-tuning
Multimodal AI
Retrieval-augmented generation (RAG)
AI model serving
Scientific computing
High-performance computing (HPC)
GPU-accelerated simulations
NVIDIA Blackwell Architecture
Built on the NVIDIA Blackwell platform, GB200 NVL72 systems are engineered for the next generation of AI computing. The platform is designed to handle increasingly large models and compute-intensive workloads while providing the high-speed communication required for distributed GPU processing.
Its architecture enables multiple GPUs to operate as a closely integrated computing environment, making it particularly valuable for large AI models where GPU-to-GPU communication and memory bandwidth are critical to overall performance.
Rack-Scale NVLink Architecture
A defining feature of the GB200 NVL72 is its high-bandwidth NVLink architecture. Rather than treating GPUs as isolated accelerators, the platform connects them through a high-speed GPU fabric designed to support intensive communication across the system.
This approach can help reduce communication bottlenecks and improve GPU utilization for demanding distributed workloads such as large-scale model training and inference.
Enterprise AI Infrastructure at Scale
The NVIDIA MGX GB200 NVL72 is designed for AI factories, hyperscale data centers, cloud service providers, research institutions, and enterprises building next-generation AI infrastructure.
By integrating a large number of Blackwell GPUs into a rack-scale system, the platform provides a foundation for deploying advanced AI models at significantly larger scale than conventional single-server architectures.
Key Highlights
NVIDIA MGX GB200 NVL72 platform
72 NVIDIA Blackwell GPUs
Rack-scale AI computing architecture
High-bandwidth NVLink GPU fabric
Designed for large-scale LLM training and inference
Optimized for generative AI and foundation models
Supports reasoning, agentic, and multimodal AI
Suitable for AI model development and production serving
Designed for hyperscale and enterprise AI infrastructure
Built for demanding GPU-accelerated and HPC workloads
With its 72-GPU Blackwell architecture and high-bandwidth NVLink fabric, the NVIDIA MGX GB200 NVL72 provides a rack-scale foundation for organizations seeking to build powerful AI infrastructure capable of supporting the next generation of large language models and advanced generative AI applications.
Frequently asked questions
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
Ready to Start?
Build Your AI Infrastructure With Confidence
Talk to our enterprise infrastructure team. Get expert guidance, GPU pricing, and a custom deployment plan — no commitment required.