NVIDIA DGX
NVIDIA DGX B200
Unified AI platform for develop-to-deploy pipelines with 8x Blackwell GPUs and 1.4 TB of HBM3e — up to 3x training and 15x inference performance over the previous generation.
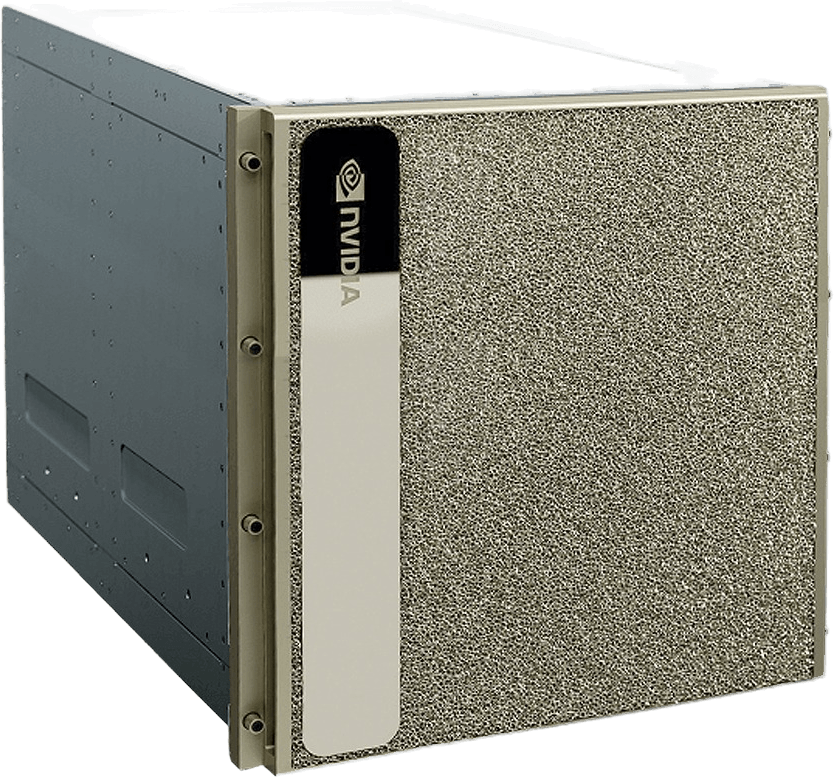
Key specifications
Ideal workloads
Foundation Model Training
Full-stack platform validated for large-scale distributed training.
Multi-Modal Workloads
Vision, language, and speech pipelines on one platform.
Technical specifications
| Chassis | NVIDIA DGX B200, 10U |
|---|---|
| CPU | 2x Intel Xeon Platinum 8570 |
| GPU | 8x NVIDIA B200 SXM, 1.4 TB HBM3e |
| System Memory | Up to 4 TB DDR5 |
| Networking | 8x OSFP 400 Gb InfiniBand |
Accelerate enterprise artificial intelligence with the NVIDIA DGX B200, a high-performance AI system built on the NVIDIA Blackwell architecture and designed for demanding LLM training, inference, fine-tuning, generative AI, and high-performance computing workloads.
The NVIDIA DGX B200 combines multiple Blackwell GPUs, high-bandwidth GPU memory, advanced NVLink connectivity, and a purpose-built system architecture into an integrated AI platform. It is engineered to provide the compute performance and GPU-to-GPU communication required to train, fine-tune, and deploy increasingly large and sophisticated AI models.
Built for Large-Scale AI
The DGX B200 is designed to support the complete AI development lifecycle, from experimentation and model training to production inference. Its high-density GPU architecture makes it suitable for:
Large language model (LLM) training
LLM inference and serving
Generative AI applications
Foundation model development
AI model fine-tuning
Retrieval-augmented generation (RAG)
AI agents and reasoning workloads
Multimodal AI
Natural language processing
Computer vision
Machine learning
Scientific computing
High-performance computing (HPC)
NVIDIA Blackwell Architecture
Powered by NVIDIA Blackwell GPUs, DGX B200 is designed for the rapidly increasing computational requirements of modern AI. Blackwell architecture provides advanced GPU acceleration for large models, complex datasets, and compute-intensive generative AI workloads.
The platform is particularly valuable for organizations that require substantial GPU compute and memory resources while maintaining a tightly integrated multi-GPU environment.
High-Bandwidth NVLink Interconnect
A core component of the DGX B200 platform is its high-speed NVLink GPU interconnect. By enabling rapid communication between GPUs within the system, NVLink helps accelerate workloads where frequent GPU-to-GPU data exchange is essential.
This architecture is especially beneficial for distributed LLM training, fine-tuning, and large-scale inference, helping reduce communication overhead and improve the efficiency of multi-GPU workloads.
Enterprise AI Infrastructure
NVIDIA DGX B200 systems are designed for enterprise data centers, AI factories, cloud providers, research institutions, and organizations building large-scale AI infrastructure.
The integrated DGX approach provides a ready foundation for AI development and deployment, allowing organizations to consolidate compute, memory, networking, and GPU acceleration into a purpose-built platform.
Ideal for AI Training and Inference
From training foundation models to deploying production AI services, the DGX B200 is engineered for demanding workloads that require substantial accelerator resources.
Organizations can use DGX B200 infrastructure to build platforms for generative AI, enterprise LLMs, AI agents, recommendation systems, computer vision, scientific research, and advanced analytics.
Key Highlights
NVIDIA DGX B200 AI system
NVIDIA Blackwell architecture
Multi-GPU high-performance computing platform
High-bandwidth GPU memory
Advanced NVLink GPU interconnect
Designed for LLM training and inference
Optimized for generative AI and foundation models
Supports fine-tuning, RAG, AI agents, and multimodal workloads
Suitable for enterprise AI and HPC
Designed for large-scale AI infrastructure and AI factory deployments
With its combination of NVIDIA Blackwell GPUs, high-bandwidth memory, and NVLink connectivity, the NVIDIA DGX B200 provides a powerful foundation for organizations looking to train, fine-tune, and deploy next-generation AI models at enterprise scale.
Frequently asked questions
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
Ready to Start?
Build Your AI Infrastructure With Confidence
Talk to our enterprise infrastructure team. Get expert guidance, GPU pricing, and a custom deployment plan — no commitment required.