AI Servers
AI Server 4 GPU
Up to 4 NVIDIA GPUs in a compact 2U chassis — maximising GPU density per rack unit for mid-scale AI training and concurrent inference.
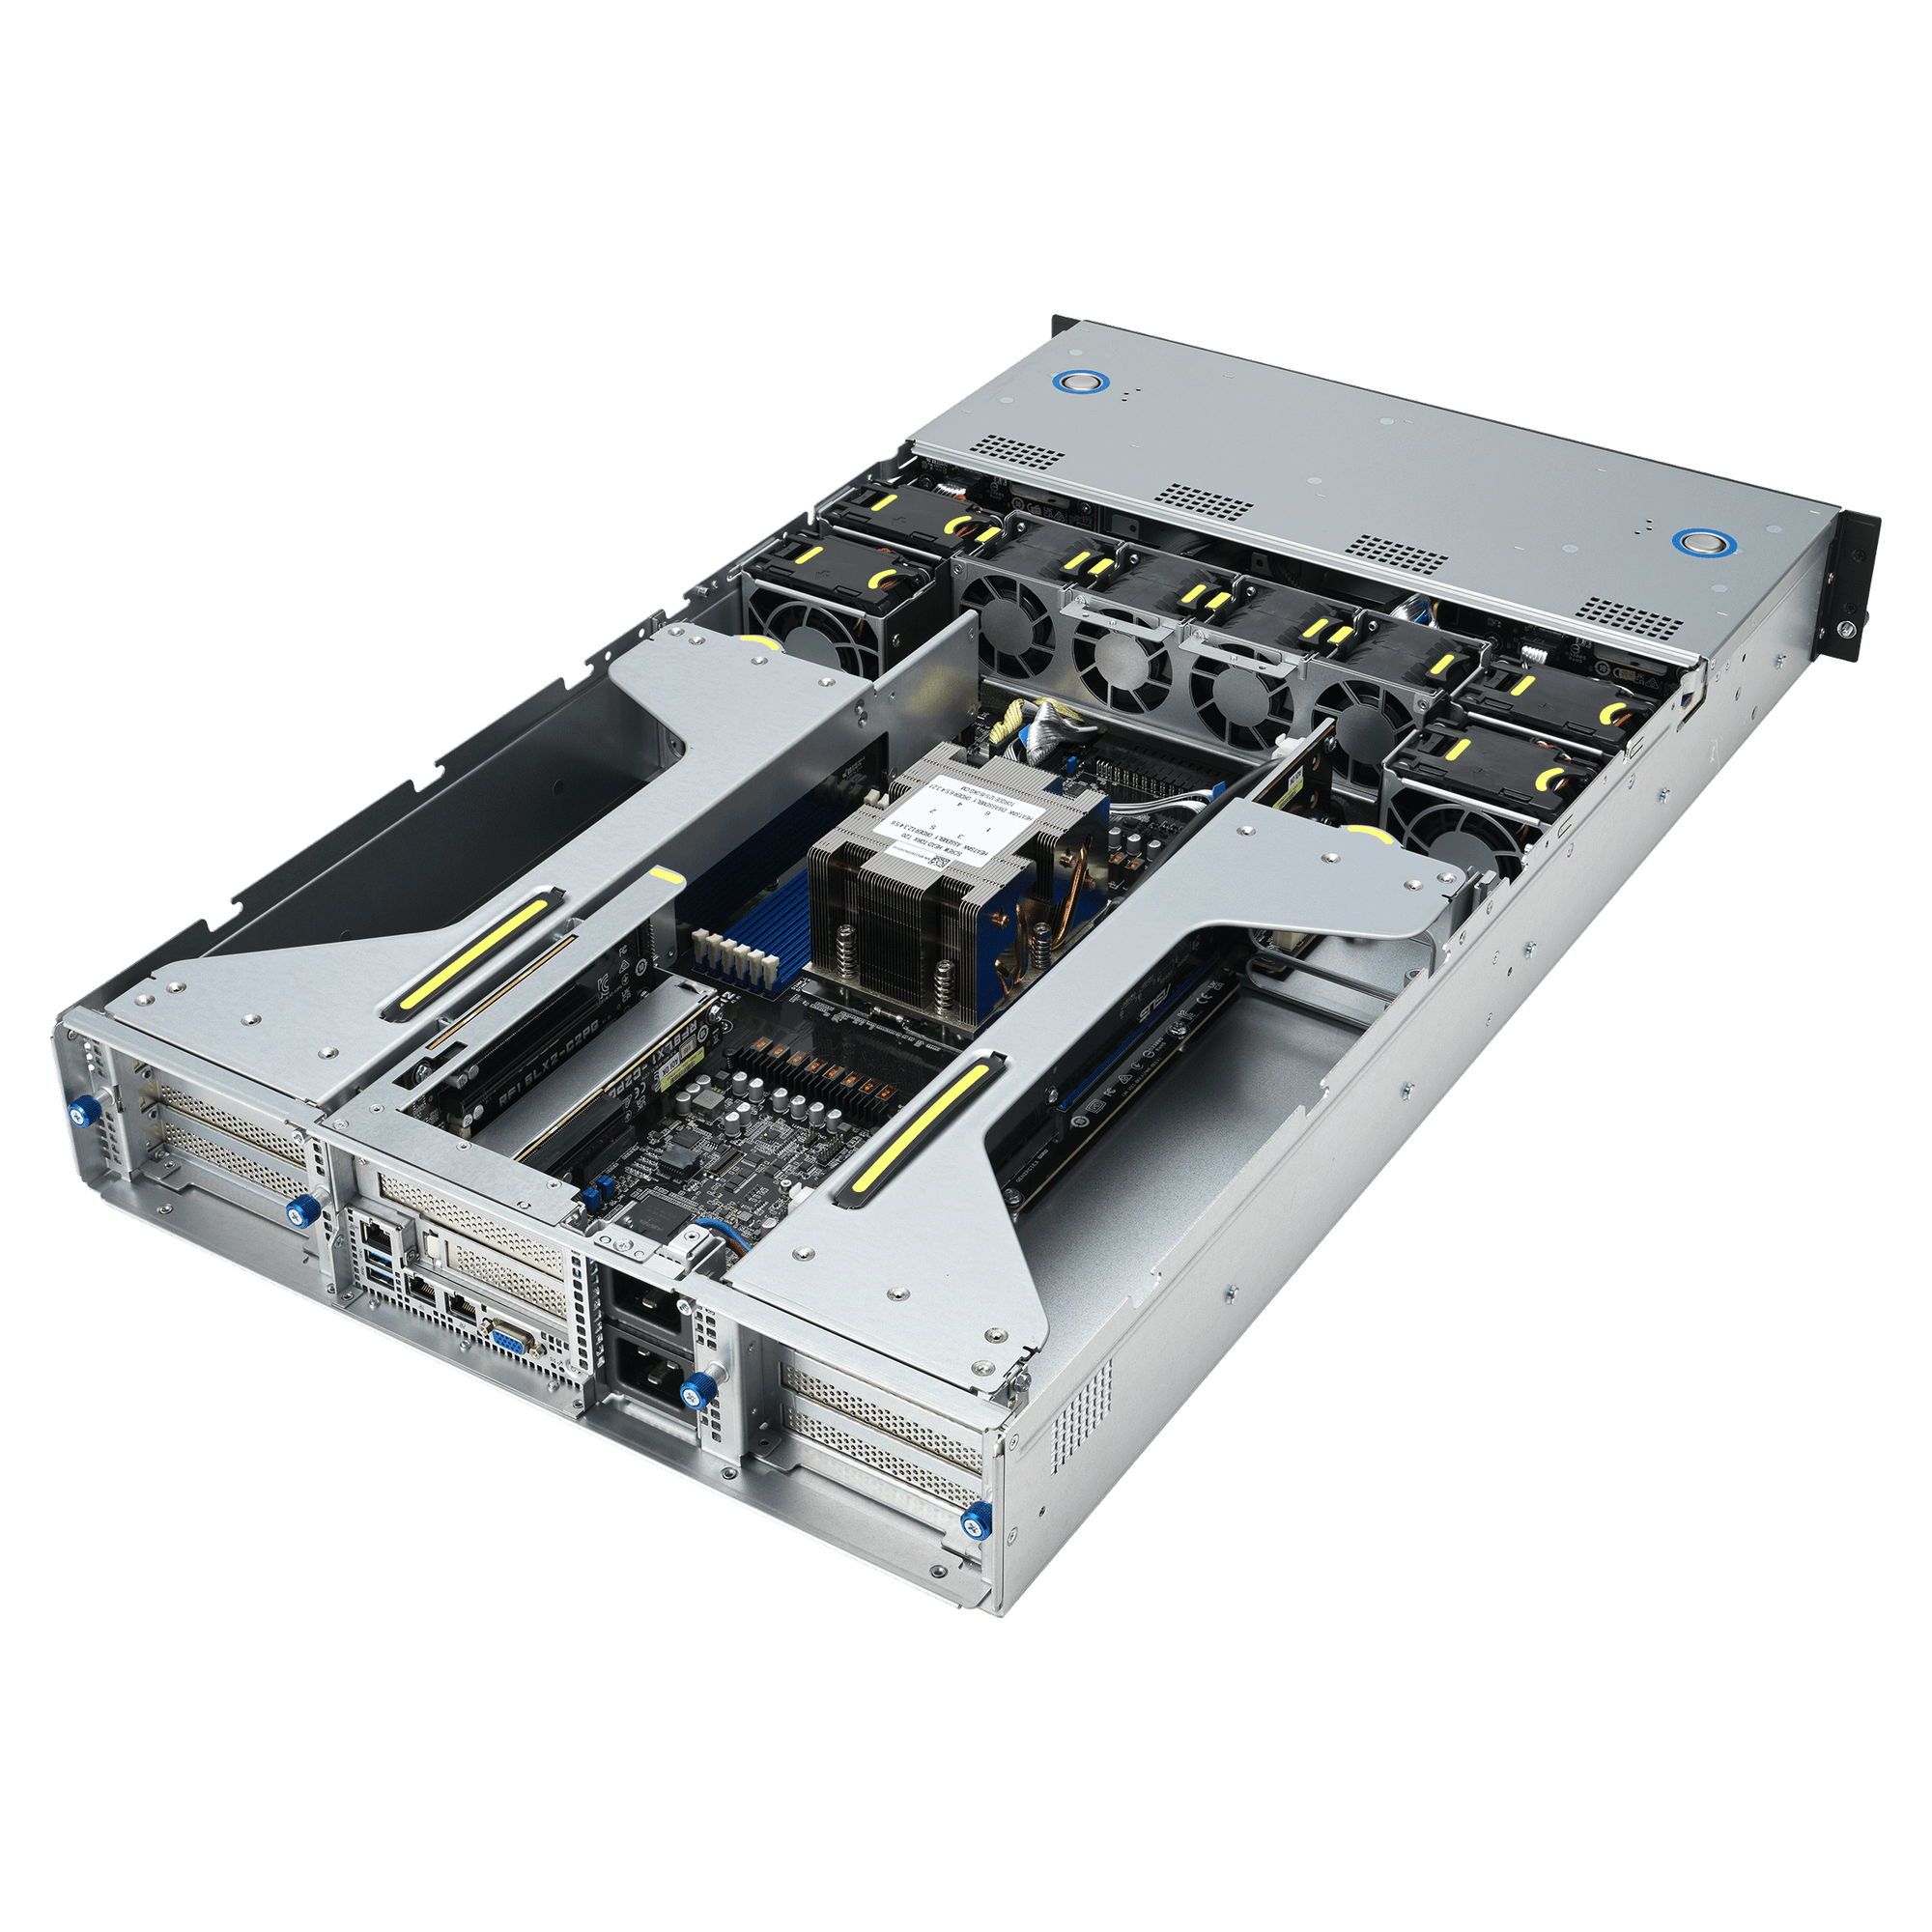
주요 사양
적합한 워크로드
Mid-Scale Training
Train models efficiently with up to 4x NVIDIA H100 NVL GPUs.
Concurrent Inference
Run multiple isolated inference workloads on one node.
기술 사양
| Chassis | 2U Rackmount |
|---|---|
| GPU Support | L4, L40S, H100 NVL — 2 to 4 GPUs |
| Memory | Up to 1.5 TB DDR5 |
Accelerate demanding artificial intelligence and machine learning workloads with a 4 GPU AI server designed for high-performance LLM training, inference, fine-tuning, generative AI, and GPU-accelerated computing. Combining four high-performance GPUs in a single server provides a powerful balance of compute density, scalability, and infrastructure efficiency for enterprises, AI developers, research organizations, and data centers.
A 4 GPU AI server is an ideal solution for workloads that require significantly more GPU compute and memory than a single- or dual-GPU system, while remaining more compact and cost-efficient than larger multi-node GPU clusters. The configuration is well suited for both AI development and production environments.
Built for Enterprise AI and Machine Learning
With four GPUs working together, these systems can accelerate a wide range of compute-intensive applications, including:
Large language model (LLM) training
LLM inference and model serving
Generative AI applications
AI model fine-tuning
Foundation model development
Retrieval-augmented generation (RAG)
AI agents and reasoning workloads
Computer vision
Natural language processing
Multimodal AI
GPU-accelerated analytics
Scientific computing and HPC
AI research and experimentation
High-Density Multi-GPU Architecture
A 4 GPU server provides a tightly integrated multi-GPU environment for applications that can distribute workloads across multiple accelerators. Depending on the selected GPU and server platform, high-speed GPU interconnect technologies can help improve communication between GPUs and accelerate workloads that require frequent data exchange.
This makes four-GPU systems particularly attractive for AI training, distributed inference, simulation, and other parallel workloads where additional GPU resources can significantly reduce processing time.
Flexible AI Infrastructure
4 GPU AI servers can be configured with different classes of NVIDIA or other accelerator hardware according to workload requirements, GPU memory needs, power constraints, and performance targets. This flexibility allows organizations to build infrastructure around specific AI applications rather than adopting a one-size-fits-all configuration.
They are suitable for enterprise data centers, AI startups, research laboratories, universities, private AI clouds, and GPU computing environments.
Key Highlights
4 GPU AI server configuration
High-performance multi-GPU architecture
Designed for LLM training and inference
Ideal for generative AI and foundation models
Supports fine-tuning, RAG, AI agents, and multimodal workloads
High GPU compute density in a single server
Suitable for AI development, research, and production
Flexible GPU and server configurations
Efficient foundation for scalable AI infrastructure
Ideal stepping stone toward larger GPU clusters
Whether you are developing large language models, deploying generative AI applications, fine-tuning foundation models, or running GPU-intensive research workloads, a 4 GPU AI server delivers the compute density and scalability needed to accelerate modern AI infrastructure.
자주 묻는 질문
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
시작할 준비가 되셨나요?
AI 인프라를 구축하세요 확신을 가지고
엔터프라이즈 인프라 팀과 상담하세요. 전문가의 조언, GPU 가격, 맞춤형 배포 계획을 받아보세요 — 별도의 약정은 필요 없습니다.