NVIDIA DGX
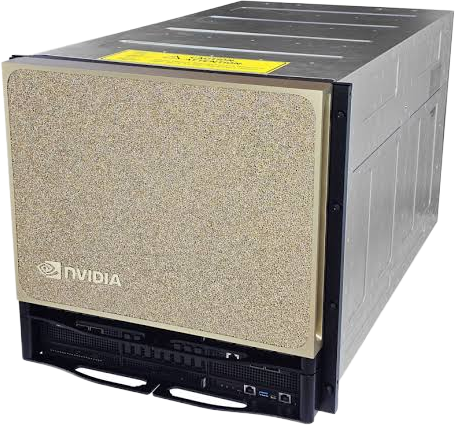
NVIDIA DGX B300
A high-performance enterprise AI supercomputer with 8x NVIDIA B300 SXM GPUs, 2.1 TB of HBM3e GPU memory, and 64 TB/s aggregate GPU memory bandwidth. Delivered and deployed across the UAE and MENA region.
주요 사양
적합한 워크로드
LLM Training & Fine-Tuning
Train and fine-tune trillion-parameter models at unprecedented speed on managed infrastructure.
Enterprise AI Inference
Deploy production inference at scale with the lowest cost per token.
Agentic AI Pipelines
Run complex reasoning and multi-agent orchestration workloads with guaranteed uptime.
기술 사양
| Chassis | NVIDIA DGX B300, 10U |
|---|---|
| CPU | 2x Intel Xeon 6776P (64-core, 2.3 GHz) |
| GPU | 8x NVIDIA B300 SXM |
| NVSwitches | 6x NVIDIA NVSwitch |
| Storage (Data) | 30 TB NVMe SSD |
| Storage (OS) | 2x 1.92 TB NVMe |
| Networking | 8x 400 Gb InfiniBand / Ethernet |
Accelerate next-generation enterprise AI with the NVIDIA DGX B300, a high-performance AI system built on the NVIDIA Blackwell Ultra platform. Designed for demanding LLM training, inference, fine-tuning, generative AI, reasoning models, and AI factory workloads, DGX B300 provides a powerful foundation for organizations developing and deploying advanced AI at scale.
The NVIDIA DGX B300 combines multiple Blackwell Ultra GPUs, high-bandwidth GPU memory, advanced NVLink connectivity, and optimized system architecture into an integrated AI computing platform. This tightly coupled design is engineered to deliver the compute performance and GPU-to-GPU communication required by increasingly large and complex AI models.
Built for Advanced LLM Workloads
DGX B300 is designed to support the full AI lifecycle, from model development and training to production inference. Its high-density GPU architecture makes it suitable for workloads including:
Large language model (LLM) training
LLM inference and serving
Generative AI
Foundation model development
AI model fine-tuning
Reasoning and agentic AI
Retrieval-augmented generation (RAG)
Multimodal AI
Natural language processing
Computer vision
AI research and experimentation
High-performance computing (HPC)
NVIDIA Blackwell Ultra Architecture
Built around NVIDIA Blackwell Ultra GPUs, DGX B300 is designed for the rapidly growing compute requirements of modern AI. The platform provides the performance, memory bandwidth, and interconnect capabilities required to process large datasets and increasingly sophisticated AI models.
Its architecture is particularly well suited to workloads where high GPU utilization and rapid communication between accelerators are critical to overall performance.
High-Bandwidth NVLink Connectivity
A key component of the DGX B300 architecture is its high-speed NVLink GPU interconnect. By enabling high-bandwidth communication between GPUs, NVLink helps support tightly coupled multi-GPU workloads and reduces communication overhead during demanding AI operations.
This is especially valuable for large-scale training, fine-tuning, and inference, where models and workloads are distributed across multiple GPUs.
Enterprise AI and AI Factory Infrastructure
The NVIDIA DGX B300 is designed for organizations building enterprise AI infrastructure, AI factories, private AI clouds, research environments, and large-scale GPU clusters.
As AI workloads move toward larger models, higher inference volumes, and more sophisticated reasoning capabilities, DGX B300 provides an integrated platform designed to accelerate deployment and simplify the infrastructure required for advanced AI computing.
Key Highlights
NVIDIA DGX B300 AI system
NVIDIA Blackwell Ultra GPU architecture
High-density multi-GPU configuration
High-bandwidth GPU memory
Advanced NVLink GPU interconnect
Designed for LLM training and inference
Optimized for generative AI and foundation models
Supports reasoning, agentic, and multimodal AI
Suitable for enterprise AI and AI factory deployments
Built for demanding accelerated computing and HPC workloads
With its combination of Blackwell Ultra GPUs, high-bandwidth memory, and advanced NVLink connectivity, the NVIDIA DGX B300 provides a powerful enterprise AI platform for organizations looking to train, fine-tune, and deploy the next generation of large-scale AI models.
자주 묻는 질문
Do you provide GPU servers for AI model training and inference?
What lead times should I expect for GPU servers?
Do you offer financing for GPU infrastructure?
How can I request a consultation or quotation?
시작할 준비가 되셨나요?
AI 인프라를 구축하세요 확신을 가지고
엔터프라이즈 인프라 팀과 상담하세요. 전문가의 조언, GPU 가격, 맞춤형 배포 계획을 받아보세요 — 별도의 약정은 필요 없습니다.